Robotics models are improving rapidly, with end-to-end models like RT-21, OpenVLA2, and π₀3 demonstrating impressive generalization capabilities. Yet these powerful models operate as black boxes - we can observe their outputs but have little insight into how they reason about the world. While significant work remains in developing better robotics models, we believe that understanding their decision-making processes could be transformative for real-world deployment. Without this understanding, deploying general-purpose robots safely and reliably remains a significant challenge.
Over the last few weeks, we've studied one such model in depth. In this research preview, we're excited to share some early results demonstrating progress towards "white-boxing" these robotics models.
Background
Since its inception for language processing, the transformer has been used to solve an increasingly broad slate of problems, from machine translation and object detection to protein structure prediction4. Perhaps unsurprisingly, transformers have also recently been shown to be effective at controlling robots. When used for robotics control, these transformers are usually referred to as vision-language-action (VLA) models1.
Most VLAs are trained by fine-tuning vision-language models (VLMs)1 on large robotics datasets like Open X-Embodiment. Through this process, VLAs learn to predict actions to execute on some robotic embodiment. Some recent techniques for predicting actions include binning2, flow matching3, and exotic tokenization schemes5.
Although modern machine learning methods deliver impressive performance, they are often completely uninterpretable - users have no insight into what caused their LLM to produce a given output. Mechanistic interpretability6 is a relatively new subfield within machine learning whereby researchers aim to address these concerns by studying the mechanisms within neural networks. Some techniques such as linear probes7, task vectors8, and persona vectors9 can, via supervision, provide insight into model internals. Additionally, unsupervised sparse dictionary learning techniques such as sparse autoencoders10 can learn human-interpretable features in LLMs from unlabeled data. Recently, similar models called transcoders11 have been shown to perform this task even more effectively.
Method
For our analysis, we trained a transcoder on π₀-FAST, an open-source VLA developed by Physical Intelligence12. To capture features containing information from all token positions and modalities, we follow Gao et al.13 and Luo et al.14 and train and evaluate models on the layer ¾ of the way through the network at layer 14.
As in Paulo et al.15, we train our transcoders with the TopK activation function and only an L2 penalty, though we do not use the skip connection out of concern that the lack of sparsity penalty may harm interpretability.
In our experiments, we swept over expansion factors in [16, 32, 64, 128] and k in [32, 64, 128].
To train our transcoders, we captured the activations of π₀-FAST over a subset of DROID16, a large-scale robotics dataset collected using a Franka Panda across a wide variety of tasks and scenes.
π₀-FAST converts data from individual time steps (including camera data, text prompt, and proprioceptive state) into tokens then passes these tokens into its VLM backbone PaliGemma17. As we perform inference with π₀-FAST, we capture the inputs and outputs of the MLP at layer 14 then save these to disk. We save 1 billion such activations for training and 250 million for validation.
During training, we use a shuffle buffer of 1 million activations and a batch size of 32,768. We evaluate performance using a handful of metrics, including the number of dead and high frequency latents.
Results
Features are generally biased towards images, but we observe a high degree of multimodality. The following metric gives a rough sense of “where” features tend to fire on average:
Weighted average firing position calculation
where:
- = Average firing position
- = Normalized weight for token i
- = Firing strength decile for i-th token
- = Position of token i
These charts show the distribution of (left) and the distribution of token types in DROID (right):
Average token index per feature weighted by firing strength
Distribution of token types in DROID
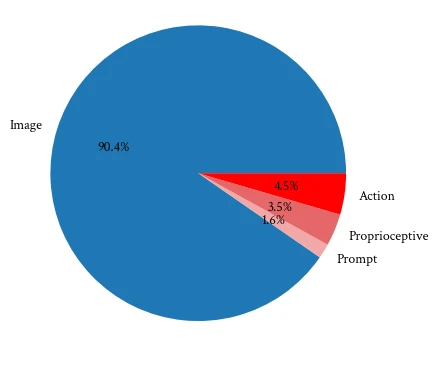
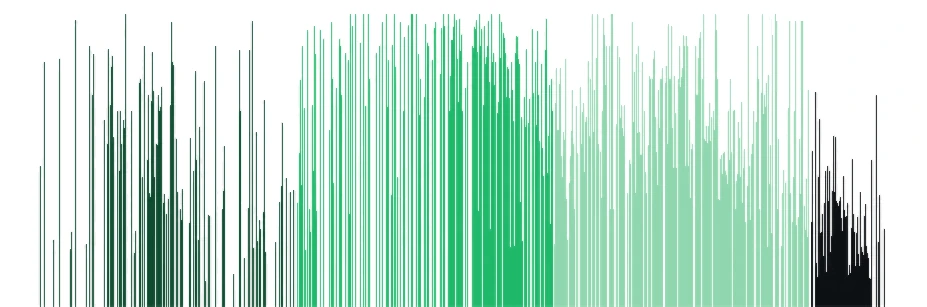
Over 98% of features fall into “image” regions in the chart above, but this obscures how multimodal features tend to be. For example, here is a non-cherrypicked example of the distribution of average firing strength across all token positions:
Average Decile by Token Index for Feature 10906
Finding Human-Interpretable Features
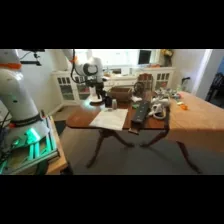
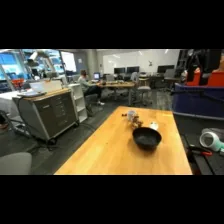
Autointerpretability flows for multimodal data are more complicated than in text-only domains. We have exciting early work on this, but in the meantime we've found some heuristics that appear to be useful for identifying “human-interpretable” features. For example, π₀-FAST's image encoding scheme scales 1280 x 720 DROID input frames down to 224 x 224 while maintaining aspect ratio. This process adds black bars to the top and bottom of every image:
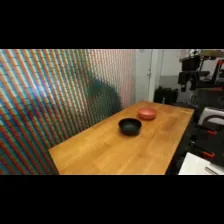
Additionally, π₀-FAST always sets the second external camera to be all black (but does not mask out the corresponding tokens). We've found that tokens that tend to fire less frequently on the all-black tokens from the second external camera and in the black-bar regions of the valid images are usually more interpretable.
Through this process, we uncovered two general classes of features that we refer to as “scene” and “ego” features. Scene features fire strongly on image tokens containing important objects or locations in external cameras, such as task objectives or key environmental landmarks.
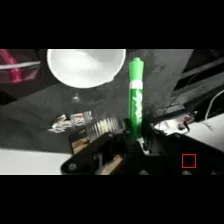
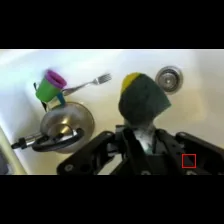
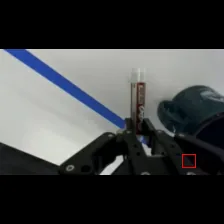
Ego features, in contrast, tend to fire on image tokens containing the robot itself. The vast majority of these fire most strongly on tokens from the wrist camera containing the end effector. Feature 4896 appears to encode when the end effector is holding a marker. Here are ten examples of image tokens that cause 4896 to fire most strongly:
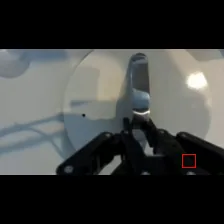
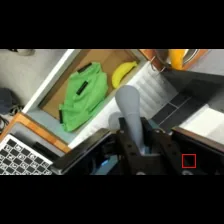
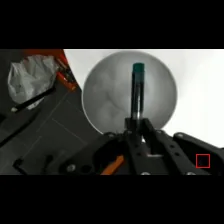
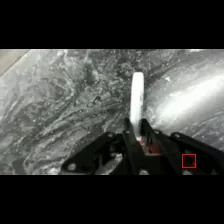
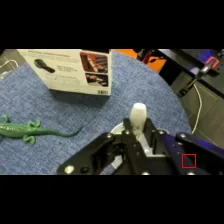
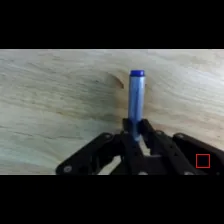
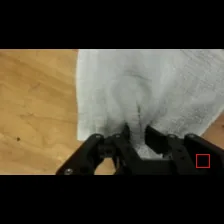
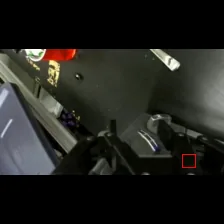
Another feature, Feature 16076, appears to fire when the end effector changes state:
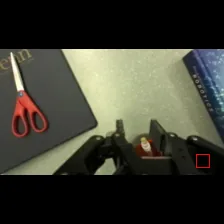
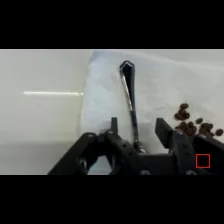
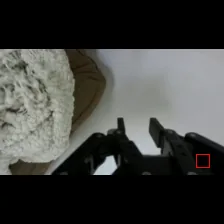
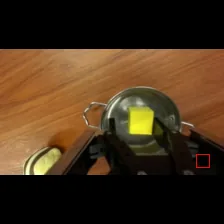
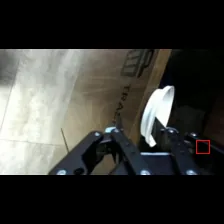
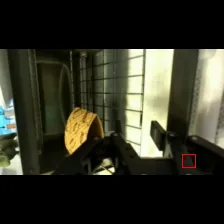
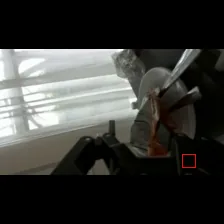
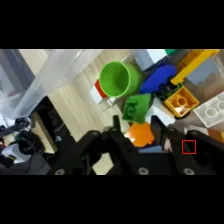
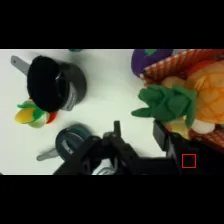
We're particularly excited about features of this class as we suspect they may have some utility for encouraging or suppressing desired behaviors. Recent work from Häon et al.18 demonstrated steering is indeed possible in VLAs like π₀-FAST, reinforcing this belief.
Limitations and Future Directions
In this research preview, we presented some small steps we've taken to study how VLAs understand the world. In the interest of expediency, we were limited in the extent of testing and evaluation we could perform of these techniques.
Because transcoder features could affect π₀-FAST's behavior across timesteps, video-level autointerpretability would be ideal - having a judge model identify similarities between video clips that cause high feature activation. However, implementing and evaluating this approach would have required a prohibitive amount of additional work for this first preview.
We did experiment with autointerpretability on text-heavy features (>95% of high-decile activations on text tokens), but our results were uninteresting. These features tend to be purely structural and fire on specific parts of speech or individual tokens rather than semantic concepts. We suspect data diversity is an issue - DROID has extremely low text diversity compared to large-scale text corpora typically used for this purpose like The Pile.19
Our most exciting findings, features that appear to encode end effector states, hint at potential steering applications. Future work should:
- Test how these features affect behavior on real hardware
- Search for similar features controlling other degrees of freedom
- Investigate features encoding user prompts for more sophisticated control
We view unsupervised dictionary learning techniques like transcoders as valuable discovery tools within a larger interpretability toolbox. While insufficient alone for fully explaining model behavior,20 they can reveal important details about how these models reason, providing a crucial first step toward safer, more controllable robotic systems.
References
- RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control.
- OpenVLA: An Open-Source Vision-Language-Action Model.
- π₀: A Vision-Language-Action Flow Model for General Robot Control.
- Protein structure prediction with AlphaFold.
- Exotic Tokenization Schemes for Vision-Language-Action Models.
- A Mechanistic Interpretability Analysis of Language Models.
- What you can cram into a single vector: Probing sentence embeddings for linguistic properties.
- Task Vectors for Model Editing.
- Persona Vectors for Language Models.
- Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet.
- Transcoders Find Interpretable Features in Language Models.
- π₀-FAST: Physical Intelligence's Vision-Language-Action Model.
- Interpretability in VLA Models.
- Vision-Language Models Create Cross-Modal Task Representations.
- Transcoders Find Interpretable LLM Feature Circuits.
- DROID: A Large-Scale In-The-Wild Robot Manipulation Dataset.
- PaliGemma: A versatile 3B VLM for transfer.
- Mechanistic Interpretability for Steering Vision Language Action Models.
- The Pile: An 800GB Dataset of Diverse Text for Language Modeling.
- Negative results for SAEs on downstream tasks.
Stay updated
Get the latest updates from Parametric.